Most AI “ears” today are effectively one-eared. Speech and audio models like Qwen-Omni or Audio Flamingo usually average stereo channels into mono before they listen, so they can tell you a siren is wailing but not that it is behind you on the right and getting louder. On October 15, 2026, Xiaomi’s audio team (the group behind its Dasheng sound models, used in Xiaomi phones, smart-home gear and car cabins) released a model aimed squarely at that gap: MiDashengLM-Spatial.
Xiaomi calls it the first open-source, end-to-end audio-language model that combines general audio understanding with spatial awareness in one network. You give it a two-channel recording and a text question; it answers in text.
Can you actually use it? Yes — right now
- License: Apache 2.0, explicitly “for both research and commercial use.” No China-only terms, no sign-up wall.
- Where: weights at huggingface.co/mispeech/midashenglm-spatial, code on GitHub, technical report on arXiv (2610.11156).
- Size: about 8B parameters — the same class as a mid-size open LLM, so a single modern GPU workstation is the realistic target, not a phone (yet).
- Setup: standard Hugging Face
transformerswithtrust_remote_code. Audio goes in before the text prompt, as a real binaural(2, T)signal. Mono still runs, but carries no direction.
What it does that typical audio AI doesn’t
The model pairs Xiaomi’s existing MiDashengLM-7B (which handles “what is this sound / what was said”) with a new spatial encoder, Spatial-Dasheng, that tracks direction, distance and motion of up to a few overlapping sources. In practice you can ask things like:
- “From which direction is the dog barking?” → front-left
- “Does the car move closer or farther away?” → getting closer
- “What does the person on your right say?” → a transcript of just that speaker
- “Write a caption describing each sound and where it is.”
To teach this, the team synthesized about 1 million spatial scenes (~13,000 hours) of binaural audio with 6 million fact-checked question–answer pairs.
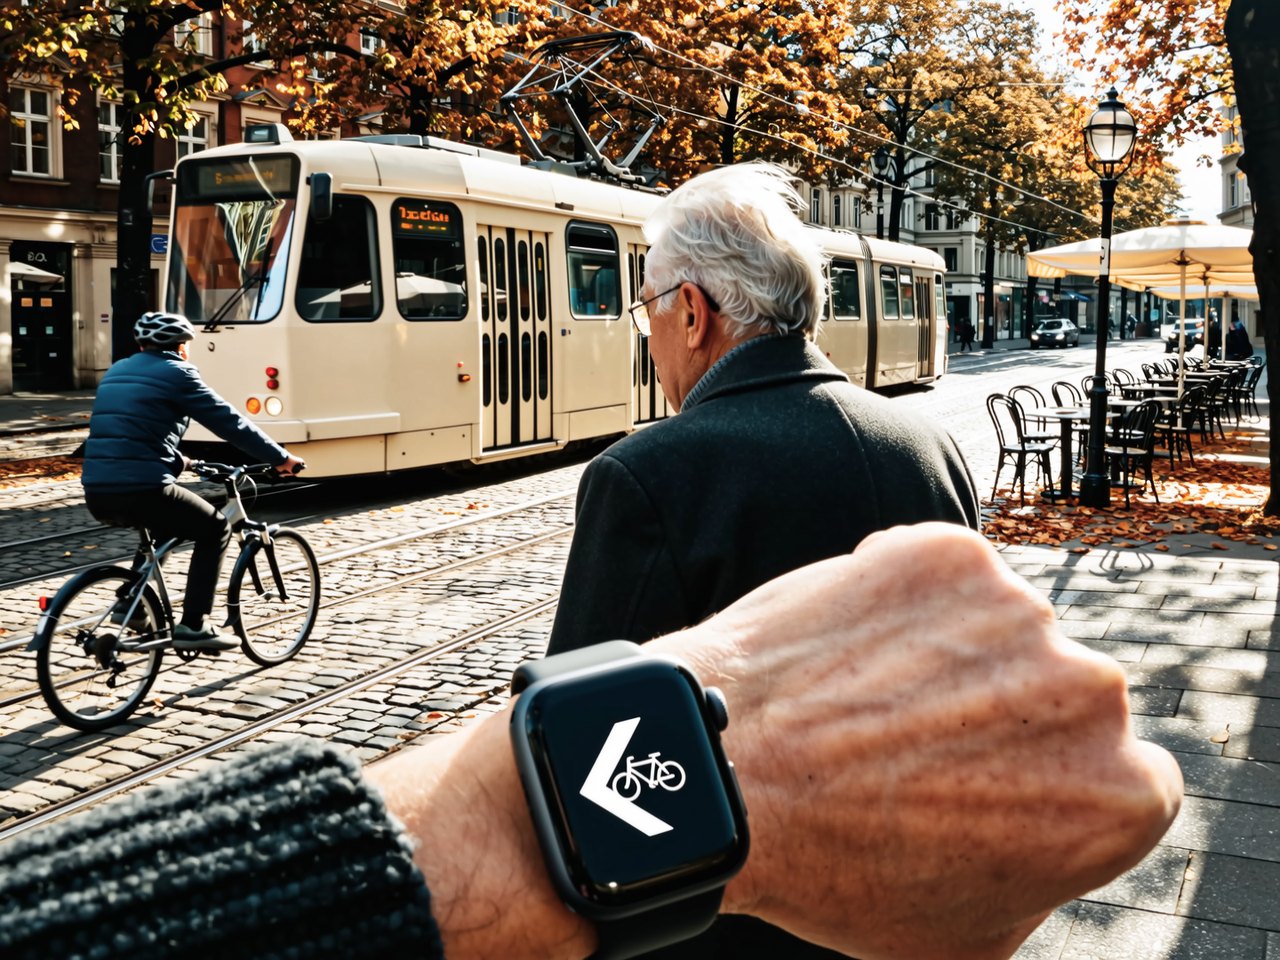
Illustration: the obvious overseas use case — a wearable that tells a hard-of-hearing pedestrian which side a bike is coming from.
How good is it? The honest numbers
On real-world spatial benchmarks, Xiaomi’s paper reports clear wins over much larger general models:
- STAR-Bench spatial reasoning: 70.3% accuracy vs 47.0% for Gemini-3.6-Flash and 44.7% for Qwen3-Omni-30B (random guess: 33.3%).
- MMAU-Pro spatial subset: 55.4% vs 48.3% for Gemini-3.6-Flash.
- Left/right swap test (flip the channels; a model that truly hears direction must flip its answer): 72.6% vs roughly 0–17% for every mono model tested — i.e., the others are guessing from context.
And it doesn’t lose its general hearing: English speech recognition on LibriSpeech test-clean is 1.8% WER, in line with other 8B audio models.
Xiaomi is upfront: coarse cues (left vs right, moving vs still, what happened first) work well; fine detail does not. Exact motion-trajectory matches stay under 20%, accuracy drops when two sources overlap, and “how many sounds are on my left?” is its weakest skill. Training data is mostly simulated rooms, and front/back and up/down are harder than left/right — just like human hearing. Treat it as a strong research-grade building block, not a finished safety product.
Why an overseas reader should care
- Accessibility builders: hearing-aid, captioning and smart-glasses teams get a free, commercially licensed base for “who is talking, and from where” features.
- Robotics and smart home: a robot or speaker that knows which room corner a crash or a voice came from is far more useful. Xiaomi itself says the model is headed for its home devices and car cabins.
- Car and security: siren direction, glass-break location, “the child in the back left seat is crying” — all fit the model’s question format.
- Game, XR and audio tooling: automatic spatial captions for binaural recordings, or QA for spatial-audio mixes.
- The bigger signal: Chinese device makers are not just open-sourcing chatbots; they are releasing specialized sensing models with permissive licenses. That lowers the cost floor for small Western hardware startups — and raises the bar for closed competitors.
If you want to try it this weekend
Record a short clip with binaural earbuds or any stereo mic pair (keep it under 60 seconds, 16 kHz is enough), load the model from Hugging Face, and ask “Where is each sound coming from?” Then swap the left and right channels and ask again. If the answer flips, you are hearing the part of this model that most audio AI still lacks.