If you have used a commercial “computer use” agent, you already know the awkward part: it often treats Excel like a touchscreen. Click, type, click again. For some apps that is the only door. For batch renames, CSV cleanups, or anything with a shell, it is theater.
Alibaba Tongyi MAI just open-sourced a stack aimed at that gap. OpenGCUA (Open Generalist Computer-Use Agent) is a harness where the model can mix visual GUI actions with programmatic code execution, and decide which path fits the intermediate state. The companion platform MAI-Gym is the evaluation and online-RL gym behind it, with claimed support for up to 20,000 parallel environment instances across phone, desktop, and web.
Papers landed on arXiv around mid-October 2026 (OpenGCUA 2610.22200, MAI-Gym 2610.20939). Code is on GitHub under Tongyi-MAI/OpenGCUA and Tongyi-MAI/MAI-Gym — the piece that matters if you actually want to wire this into a research or product loop.
What the benchmarks claim
On OSWorld-v2, OpenGCUA’s full configuration improved task scores for all eight evaluated models, including frontier computer-use systems named in the abstract as GPT-6 Astra and Claude Opus 5, plus Chinese API models such as Qwen3.8-Max. Mean partial score rose by about +19.6 points versus batched GUI-only execution, and reported steps per task fell by roughly 53%.
That is a harness win as much as a model win: same models, better scaffolding. The paper also flags a real-device efficiency gap — on four macOS tasks under their harness, selected Qwen3.8-Max runs used about 19.4× as many reported reasoning tokens as GPT-6 Astra. Useful if you care about cost, not only success rate.
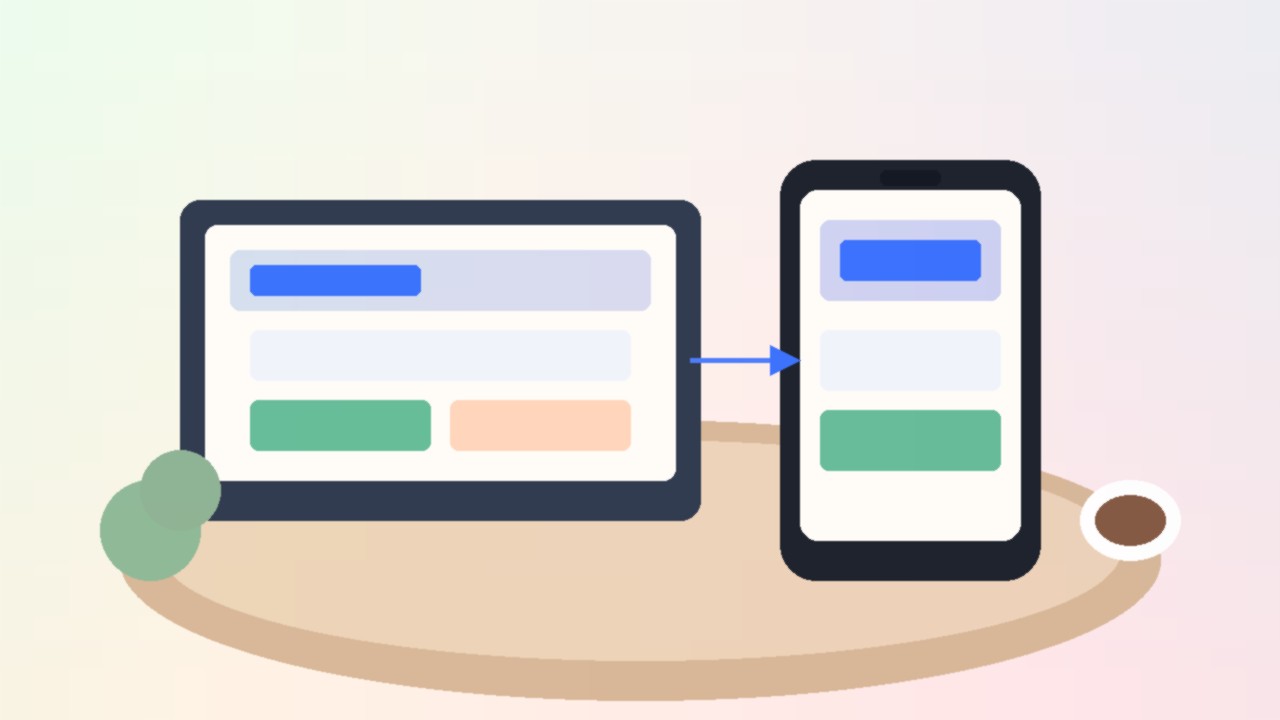
Illustration: MAI-Gym’s sim-to-real pitch — practice on a resettable mocked ticketing app, then measure transfer on a physical phone.
MAI-Gym and the 9B open agent
MAI-Gym is the heavier engineering story. It unifies evaluation, data collection, and online RL so the agent you train is the agent you score. The paper reports a trained MAI-Gym-9B policy (from a Qwen3.5-9B warm start) at 78.4% on MobileWorld and 76.2% on OSWorld-Verified — positioned as open SOTA under 10B for those GUI-agent settings. They also report clone-to-real transfer: RL in a mocked Chinese train-ticketing app raised success on the real app on a physical phone from 28.8% to 48.1% across 52 paired tasks.
Released resources named in the MAI-Gym abstract include the framework, synthesis skills, mocked apps, about 2,000 verified tasks, and a model checkpoint. Treat those numbers as paper claims until you clone the repos and check the README licenses and hardware needs — this is research infra, not a one-click SaaS.
You can clone OpenGCUA and MAI-Gym, read the arXiv reports, and reuse the SDK / harness ideas if you already run desktop or mobile agents. This is not a consumer product that installs like a browser extension; scaling to thousands of parallel VMs is a lab/cloud problem. Verify licenses, API keys for any frontier models you plug in, and whether the released 9B checkpoint matches the paper’s reported eval protocol.
Why an overseas builder should care
Most computer-use demos you see from US labs still emphasize pure screenshot→click loops. OpenGCUA’s public thesis is that generalist computer use should let the model choose observation and action modes — including code — the way a competent human does. If you ship internal agents for ops, finance ops, or QA, that design matches how your best engineers already work.
Practically: start with the OpenGCUA repo and the OSWorld-v2 trajectory release if you want to reproduce the harness lift on a model you already pay for. Reach for MAI-Gym if you need shared eval/train infrastructure or the mocked-app synthesis loop. Ignore the press framing; the usable test is whether your next spreadsheet or file-batch task finishes in fewer steps with a GUI+code agent than with clicks alone.