Start with what you can actually run. Spark-X2.6-4B is a dense 4B on-device model under Apache-2.0, same architecture family as X2.5-4B with improved post-training. Artifacts are globally reachable: Hugging Face org XHToken (Base, FP8, INT8, GGUF), GitHub XHToken/Spark-X2.6, and Ollama as SparkLLM/Spark-X2.6-4B. ModelScope mirrors cover China. Vendor materials claim three thinking budgets — none / low / high — plus coding, agent, long-context, and multilingual gains; the series inherits a native ~1M context lineage from X2.5 and claims 200+ languages.
The cloud headline is the domestic-silicon training narrative. Spark-X2.6 is described as a MoE with 293B total parameters and about 30B activated (293B-A30B), 1M context, trained on fully domestic Chinese compute. iFlytek chairman Liu Qingfeng claimed Spark is the only major model fully domestic-trained, contrasting others that still lean on NVIDIA stacks. The company pitch: first code + agent capability breakthrough on that fully domestic training path, with domestic long-horizon training efficiency fixes (dynamic parallel training aimed at memory-bandwidth limits) and heterogeneous distributed inference for domestic clusters. Treat those as company / press claims, not independent audits.
Promo cloud API pricing
On the official Spark API page, limited-time (限时) promo rates are listed as roughly 60% off: input ¥0.9 / M tokens, cache hit ¥0.08 / M, output ¥3.6 / M. Try / API entry: xinghuo.xfyun.cn/sparkapi. Overseas builders should assume Chinese account and payment friction until proven otherwise — the open 4B is the cleaner path if you just want weights.
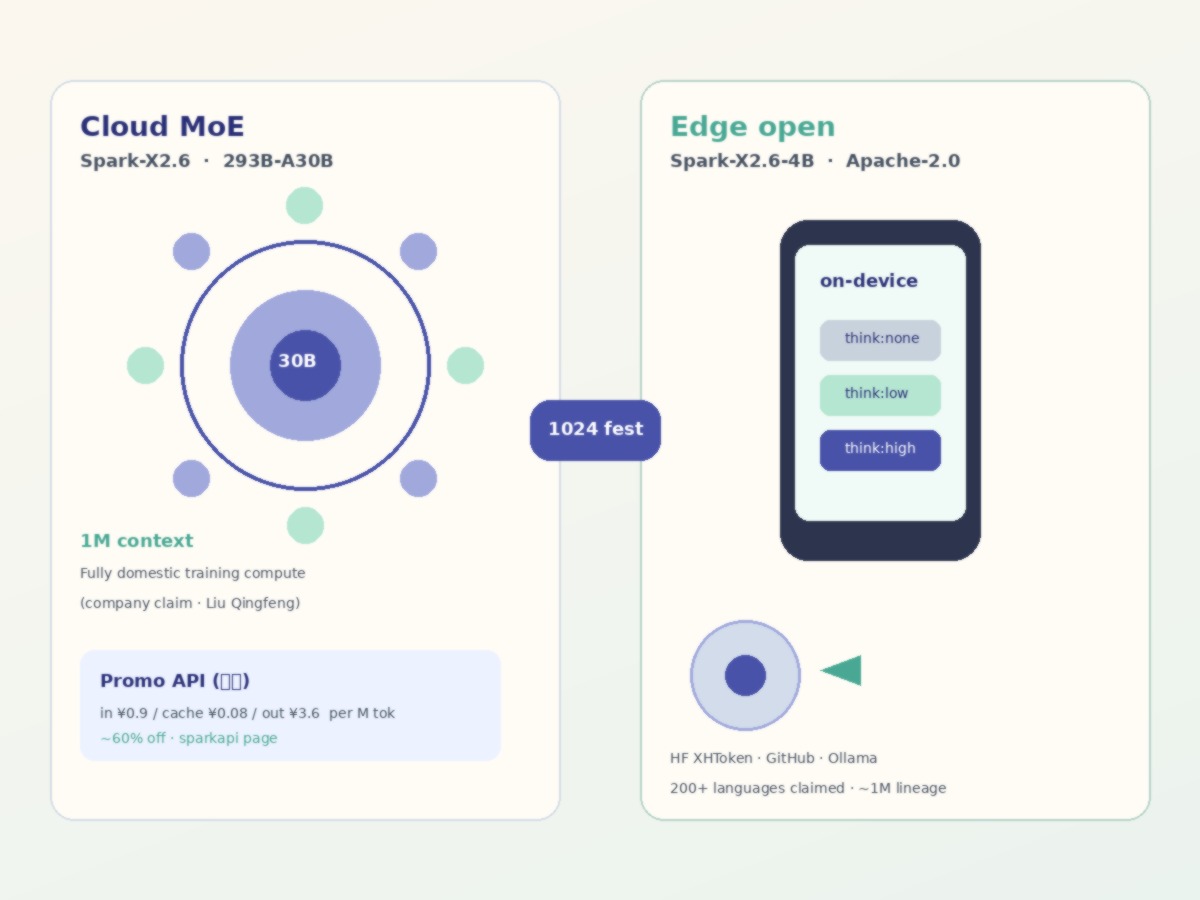
Illustration: cloud MoE (293B-A30B, 1M ctx, domestic-train claim + promo API) beside the open 4B edge model with none/low/high thinking budgets.
Yes for the 4B open artifacts: HF XHToken, GitHub, and Ollama are globally usable under Apache-2.0. The cloud MoE / Spark API is a different story — Chinese signup and payment are the realistic default. Press notes that X2.5-4B has ranked in the top-4 global on-device model downloads since Sep 1, 2026 (vendor/press claim); X2.6-4B is the incremental post-training drop on that same distribution lane.
Where to look
- Weights: huggingface.co/XHToken (Spark-X2.6-4B, GGUF, FP8, INT8, Base)
- Code: github.com/XHToken/Spark-X2.6 (Apache-2.0)
- Ollama:
SparkLLM/Spark-X2.6-4B - Cloud try / API: xinghuo.xfyun.cn/sparkapi
- China mirrors: ModelScope (vendor listing)
Honest caveats
- Vendor benchmarks — coding/agent/long-context/multilingual “gains,” top-4 download rank, and domestic-only training claims come from iFlytek / press coverage, not third-party audits here.
- Cloud vs open — the MoE story is API/product; the downloadable overseas path is the dense 4B.
- Account friction — Spark cloud API may need a Chinese account and local payment; promo rates are 限时 and can change.
- Thinking budgets — none/low/high are vendor-described knobs; validate latency and quality on your own traces before shipping agents.
For overseas engineers tracking China’s domestic-compute narrative, Spark X2.6 is a clean two-track release: a cloud MoE that argues the training stack no longer needs NVIDIA, and a small open model you can actually pull tonight.