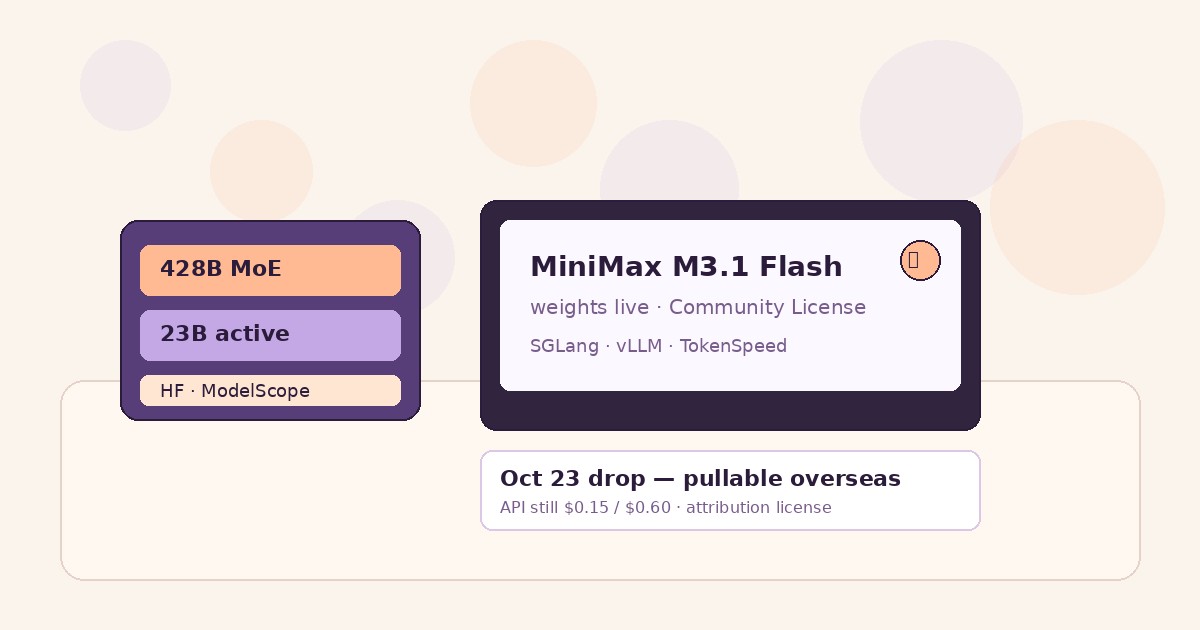
Four days after the API launch, the downloadable path arrived. The Hugging Face repo MiniMaxAI/MiniMax-M3.1-Flash and ModelScope MiniMax/MiniMax-M3.1-Flash list a native multimodal mixture-of-experts model: text, image, and video in, text out, up to 1M tokens of context. Card figures: roughly 428B parameters total with about 23B activated per token.
Efficiency knobs called out on the card: MiniMax Sparse Attention (MSA) throughout (first three full-attention layers replaced), quantization-aware training on routed experts and attention paths, and DSpark speculative decoding with a draft head in the release. Recommended local serving: SGLang, vLLM, and TokenSpeed; FlagOS is listed for multi-chip paths. Sampling guidance on the card: temperature=1.0, top_p=0.95, plus reasoning_effort knobs (low … max).
License: readable, not OSI open source
This is the detail overseas teams needed on Oct 20 when license was still TBD. Public write-ups of the MiniMax Community License describe a grant that starts from non-commercial use, then allows commercial use with conditions: show attribution such as “Built with MiniMax M3.1-Flash,” send a one-time notice under ~$20M yearly revenue, and get prior written approval above that. Fine-tunes and hosted commercial use count. Treat that as a summary — read the license file on the HF repo before you ship. It is not an OSI open-source license.
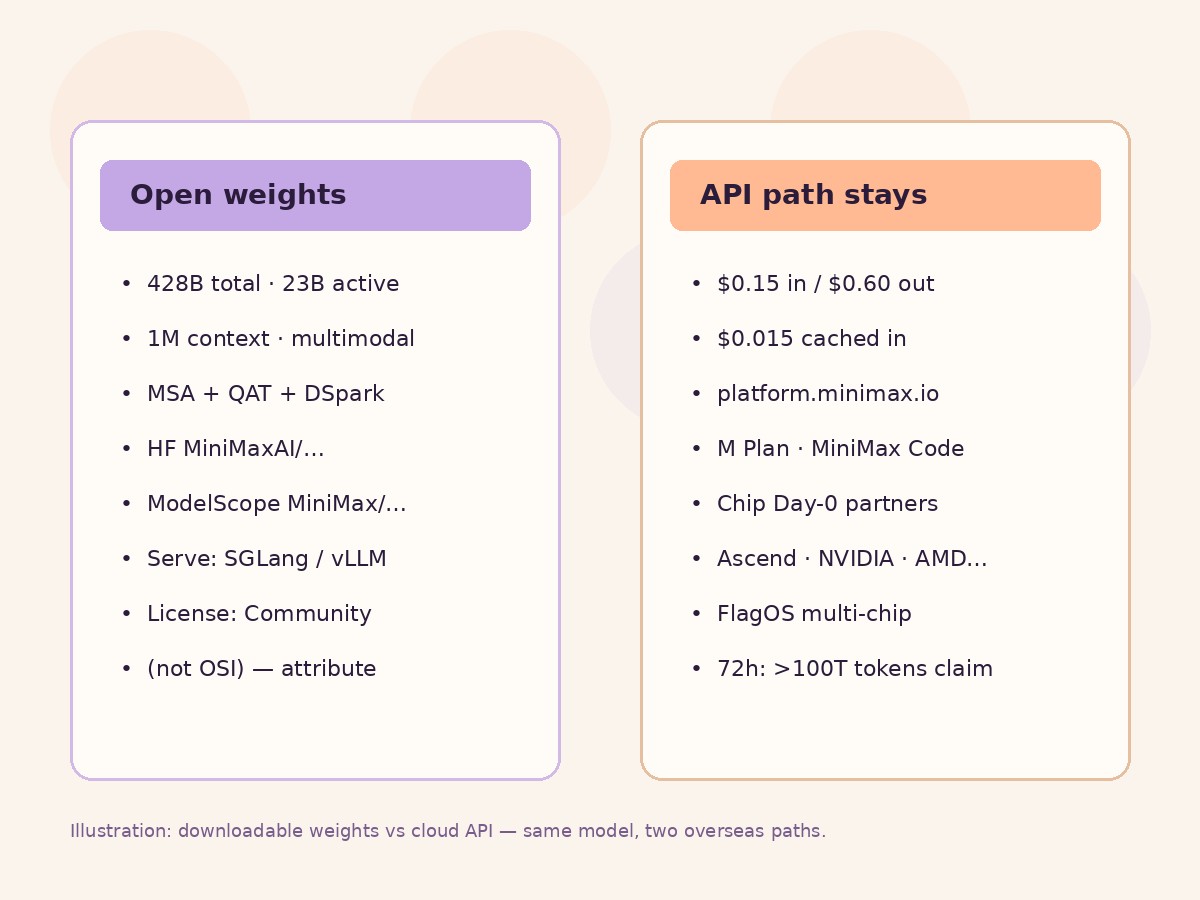
Illustration: weights path (HF / ModelScope / Community License / SGLang·vLLM) beside the unchanged API path ($0.15 / $0.60 / $0.015).
Yes for weights and recipes if the Community License fits your use — HF and ModelScope are globally reachable; SGLang/vLLM cookbooks are the practical serve path. The hosted API remains on platform.minimax.io at $0.15 input / $0.60 output / $0.015 cached per 1M tokens (CN ¥1 / ¥4 / ¥0.1 on the earlier launch). Large MoE self-host still means serious GPU memory; most overseas builders will sample via API first.
What press and the company claim today
Chinese press (IT之家 / ifeng, Yicai) says MiniMax announced the weight drop on Oct 23 and claimed >100 trillion tokens processed by real users in the first ~72 hours after the Oct 19 API launch — treat as a company/press figure. The same coverage lists Day-0 chip and cloud partners (Huawei Ascend, T-head, Kunlunxin, Moore Threads, NVIDIA, AMD, Together AI, Fireworks, and others) plus vLLM, SGLang, FlagOS, Hugging Face, and ModelScope cooperation. Vendor agentic scores on the HF card (BankerToolBench 76.2, DeepSWE v1.1 73.7%, OSWorld 2.0 61.7, Agents’ Last Exam 29.6, CyberGym 82.2) remain company-reported; our Oct 20 piece already flagged independent hallucination caveats from Artificial Analysis-style evaluations.
Where to look
- Weights (HF): huggingface.co/MiniMaxAI/MiniMax-M3.1-Flash
- Weights (ModelScope): modelscope.cn/models/MiniMax/MiniMax-M3.1-Flash
- API / product: platform.minimax.io · launch blog
- Prior coverage: China Hot Tech — Oct 20 API launch
Honest caveats
- License — Community License with attribution and revenue thresholds; not Apache/MIT. Read the file before commercial deploy.
- Vendor benches — agentic/coding/cyber scores and “100T tokens in 72h” are company/press claims, not audits here.
- Self-host cost — 428B-class MoE weights are heavy; recipes help, but GPU budget is the real gate.
- Reliability — earlier independent notes on hallucination still matter for agent pipelines; validate on your traces.
For overseas readers who bookmarked the Oct 20 “weights due Oct 23” line: the drop is real, the license is clear enough to decide, and the API price floor did not move. Pull if the Community License works for you; otherwise keep using the flat-rate endpoint.