Nanbeige4.3-33B is not pitched as a general chat toy. The card frames it as a high-capacity teacher agent first: ship a strong ~30B open model for coding and professional cowork, then distill those agent skills into smaller siblings. Contact on the card is nanbeige@kanzhun.com (Boss Zhipin / 看准网 related). Chinese non-mainstream coverage on AI热报 (airebao) and similar roundups landed around Oct 25, 2026, matching the HF upload.
Can you actually pull and run it?
Yes, commercially, with the usual ML caveats. The Hugging Face README front-matter sets license: apache-2.0; the API tag is license:apache-2.0. Weights are public (not gated), BF16, about 66 GB across 14 safetensors shards on the main tree — so a single consumer GPU is not the realistic serve path. The card’s SGLang and vLLM examples both use tensor parallel size 4. Languages declared: English and Chinese. A separate Nanbeige4.3-33B-Base repo exists for post-training from scratch.
Inference paths on the card: Hugging Face Transformers (trust_remote_code=True), SGLang, and vLLM. Chat template knobs matter for agent work:
- enable_thinking — default on; set
Falsefor non-thinking mode. - preserve_thinking — recommend
Truefor multi-turn tool use, office tasks, and code agents;Falsefor plain chat/Q&A. Vendor benches usedpreserve_thinking=true. - tool_call_format — prefer
xml;jsonalso supported.
Suggested sampling: agentic/tool tasks at temperature 1.0 / top_p 0.95 / up to 65,536 new tokens; reasoning/chat at 0.6 / 0.95 / up to 262,144. Max context: 524,288 tokens (512K).
Nanbeige4.3 positions 33B as the flagship teacher that will anchor distillation into smaller models (the card explicitly names Nanbeige4.3-3B as an example). If you only need a strong open ~30B agent today, pull 33B; if you are waiting for a laptop-class distill, that is still future work.
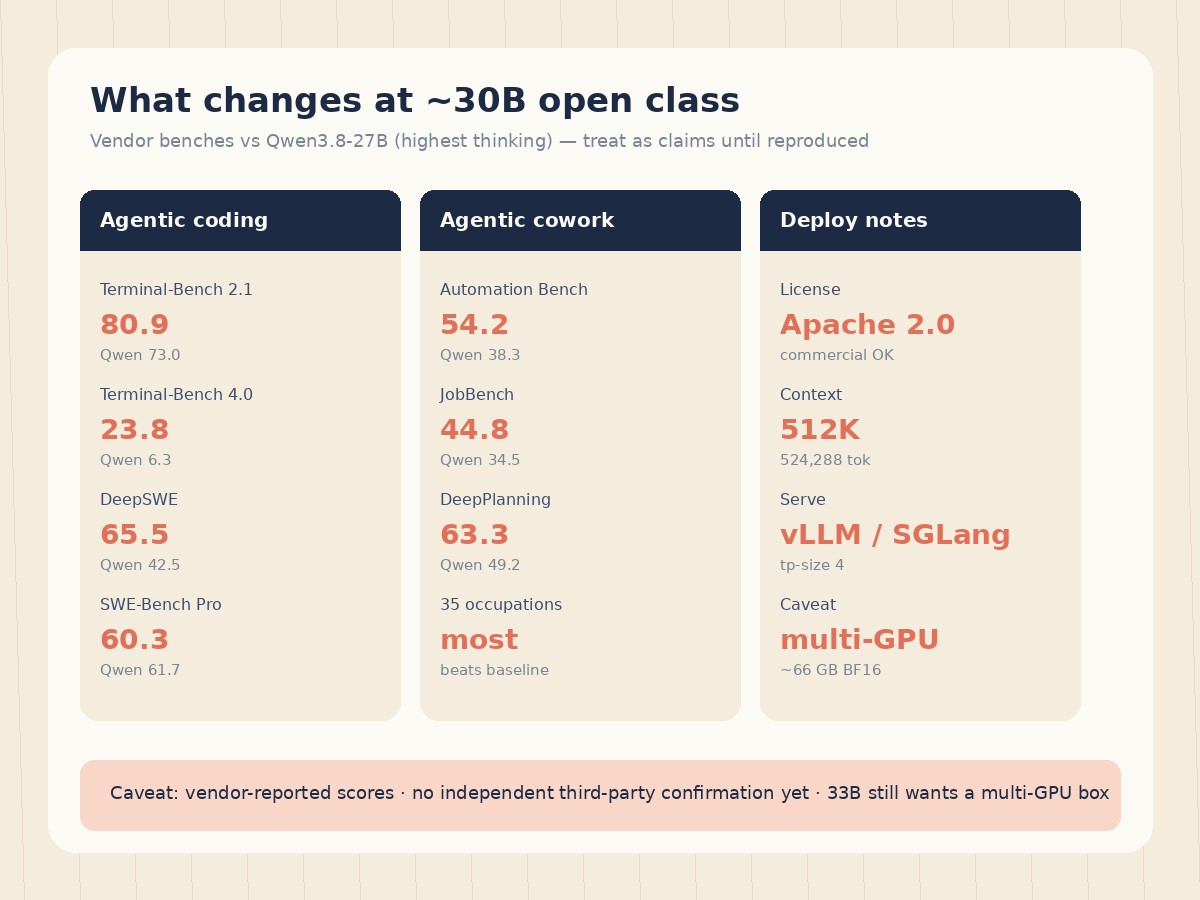
Vendor-reported scores at highest thinking effort versus Qwen3.8-27B, Muse-Glimmer-30B, and Gemma4-31B. Not independent third-party confirmation.
What the card claims against ~30B peers
Comparisons are against Qwen3.8-27B, Muse-Glimmer-30B, and Gemma4-31B, all at highest thinking effort, same harness/hparams per the card. Selected agentic coding highlights (Nanbeige vs Qwen):
- Terminal-Bench 2.1: 80.9 vs 73.0
- Terminal-Bench 4.0: 23.8 vs 6.3
- DeepSWE: 65.5 vs 42.5
- SWE-Bench Pro: 60.3 vs 61.7 (one of the few where Qwen edges ahead)
- Also listed: SWE-Atlas-QnA 50.8, NL2Repo 53.0, Scicode 52.6, SkillsBench 61.1 — all ahead of Qwen on the card.
Agentic cowork highlights:
- Automation Bench: 54.2 vs Qwen 38.3
- JobBench: 44.8 vs 34.5 — card says it outperforms the baseline on most of 35 occupations
- DeepPlanning 63.3 vs 49.2; Toolathlon-Verified 70.4 vs 68.5; Claw-Eval pass³ 78.3 vs 75.2
- GDPval 84.8 vs 86.4 (Qwen slightly ahead); Tau3-Bench nearly tied (48.8 vs 48.5)
Reasoning row on the card is competitive rather than dominant (GPQA Diamond 89.5 vs Qwen 89.2 / Gemma 91.3; AIME 2026 95.2). The story the lab wants you to hear is agentic coding + cowork, not pure STEM Olympiad.
Honest caveats
- Vendor benches only — numbers come from the Nanbeige model card. No independent third-party confirmation yet; reproduce before you trust a ranking.
- Hardware is real — ~33B BF16 (~66 GB weights); card examples assume multi-GPU (tp-size 4). Quantization can shrink VRAM, but that is your stack, not a shipped guarantee.
- trust_remote_code — Transformers path asks for it; review the custom code before production.
- SWE-Bench Pro is close — Qwen3.8-27B still leads that one on the card (61.7 vs 60.3); do not market “wins every coding bench.”
- Distill not out yet — Nanbeige4.3-3B is a stated direction, not a download today.
Bottom line for overseas engineers who can actually pull weights: Nanbeige4.3-33B is a rare Apache-2.0 ~30B-class open teacher aimed at coding agents and professional cowork, with a 512K window and runnable Transformers / SGLang / vLLM paths. Download it if you have the GPUs and want an open teacher before the small distill ships — and treat the scoreboard as the lab’s until you run your own harness.